Benchmarks / Remote Labor Index
Remote Labor Index (RLI)
Built by CAIS and Scale AI · released Oct 2025
Real freelance projects, collected from professionals on Upwork, that an agent must deliver end to end. Trained human evaluators compare each AI deliverable with the deliverable that a paid professional made.
Frontier
21.3%
Automation rate
Opus 5.5
7 Oct 2026 · Source: Scale AI (benchmark maintainers)
Rank 1 on the Scale board, entry added 2026-10-07. The CAIS dashboard shows the same 21.25 (21.3% in its headline). The board names no scaffold for this row and gives no confidence interval, so the 0.42-point lead over GPT 6 Astra is small.
The best result is at 20–60% of the ceiling, or at 50–100% of human parity.
What it measures
Whether a reasonable client would accept the agent's deliverable, compared with a gold-standard deliverable from a professional freelancer. Projects come from 23 Upwork domains, for example 3D and CAD, architecture, graphic design, video and animation, audio, data analysis, and web apps.
Automation rate: Share of projects where the AI deliverable is judged at least as good as the professional deliverable. Higher is better.
Status compares the frontier with a ceiling of 100%.
Facts
- Grain
- Project level: whole projects judged by an acceptance standard
- Environment
- cli, computer-use
- Grading
- human-expert, pairwise-human
- Tasks
- 240
- Human reference
- A professional freelancer's accepted deliverable. Mean human completion time 28.9 hours (median 11.5 hours). Mean project value $632.60 (median $200).
- Contamination
- Leaderboard scores use a private set of 230 projects.
- Reuse
- Scores come from 230 private projects. 10 public projects and the open-source evaluation platform are released for qualitative analysis. (cite-only)
Limits to keep in mind
Recorded results
A selection that shows the frontier over time. The full leaderboard is at the source.
Where sources disagree
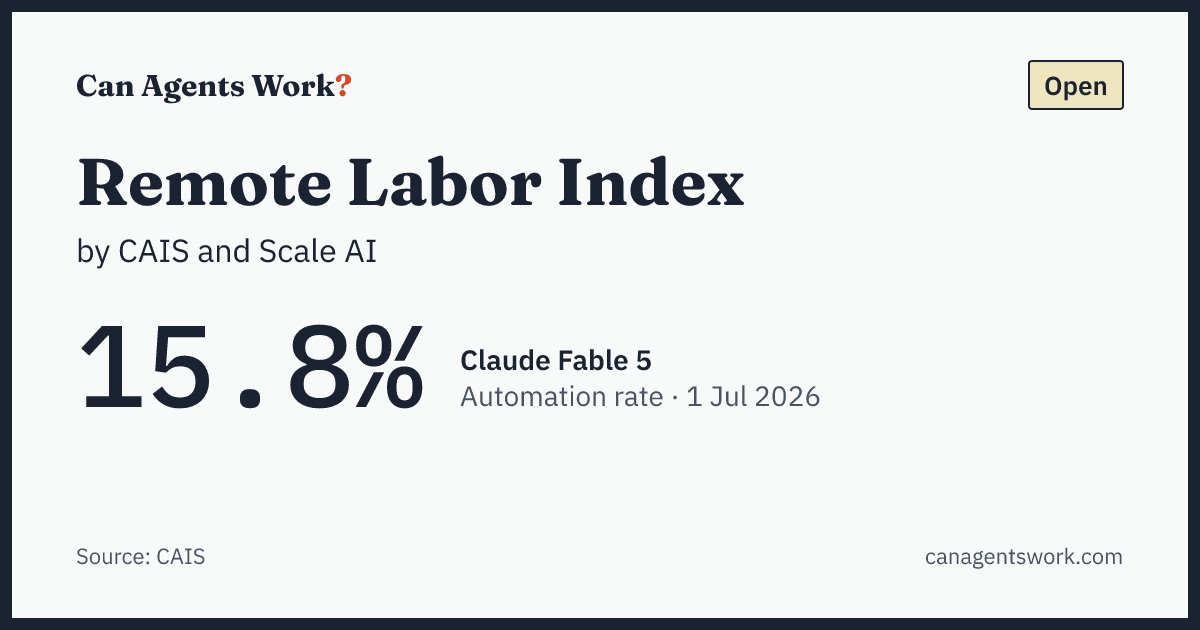
CAIS, a co-author of the benchmark, reports 15.8% for Claude Fable 5, and on 2026-10-10 the Scale leaderboard and the CAIS dashboard both show 15.83. Aggregator pages report 16.1%. The earliest 16.1% we found is a news digest dated 2026-07-05 that quotes a social-media summary of the CAIS post. We did not find a primary source for 16.1%, so the cause is still open.
- 15.8 — safe.ai (primary) · CAIS post dated 2026-07-01, read again 2026-10-10.
- 15.83 — labs.scale.com (primary) · Scale leaderboard row "Fable 5", entry added 2026-07-01, seen 2026-10-10.
- 15.83 — dashboard.safe.ai (primary) · CAIS dashboard, Automation section, row "Fable 5", seen 2026-10-10.
- 16.1 — www.benchleader.com (third-party) · BenchLeader page, seen 2026-09-23 and again 2026-10-10 (all its other RLI rows match the Scale board).
- 16.1 — ai-intensify.com (third-party) · News article, seen 2026-09-23.
- 16.1 — www.ai-primer.com (third-party) · News digest dated 2026-07-05, seen 2026-10-10. It attributes 16.1% to a social-media summary of the CAIS post.
We show 15.8. Status: open.
Timeline
Where it sits in the atlas
Work ladder: Context only. It spans many occupations, so it does not set the step of a job family. How the ladder works
Design, media, and writingArchitecture and engineering (partial)Data and analytics (partial)Software engineering (partial)
Go to the source
- Website www.remotelabor.ai
- Paper arxiv.org
- Full leaderboard labs.scale.com
- Announcement safe.ai
Last checked 10 Oct 2026 against 6 primary sources. See an error? Tell us.
How to cite
Credit the original work first: Remote Labor Index by CAIS and Scale AI (https://arxiv.org/abs/2510.26787).
Then, if you used this page:
Can Agents Work. "Remote Labor Index: frontier results and sources." https://canagentswork.com/benchmarks/remote-labor-index/ (accessed 2026-10-11). CC BY 4.0.@misc{caw-remote-labor-index,
title = {{Remote Labor Index: frontier results and sources}},
author = {{Can Agents Work}},
year = {2026},
howpublished = {\url{https://canagentswork.com/benchmarks/remote-labor-index/}},
note = {Accessed 2026-10-11. CC BY 4.0}
}